See it
Real screens from a running stack.
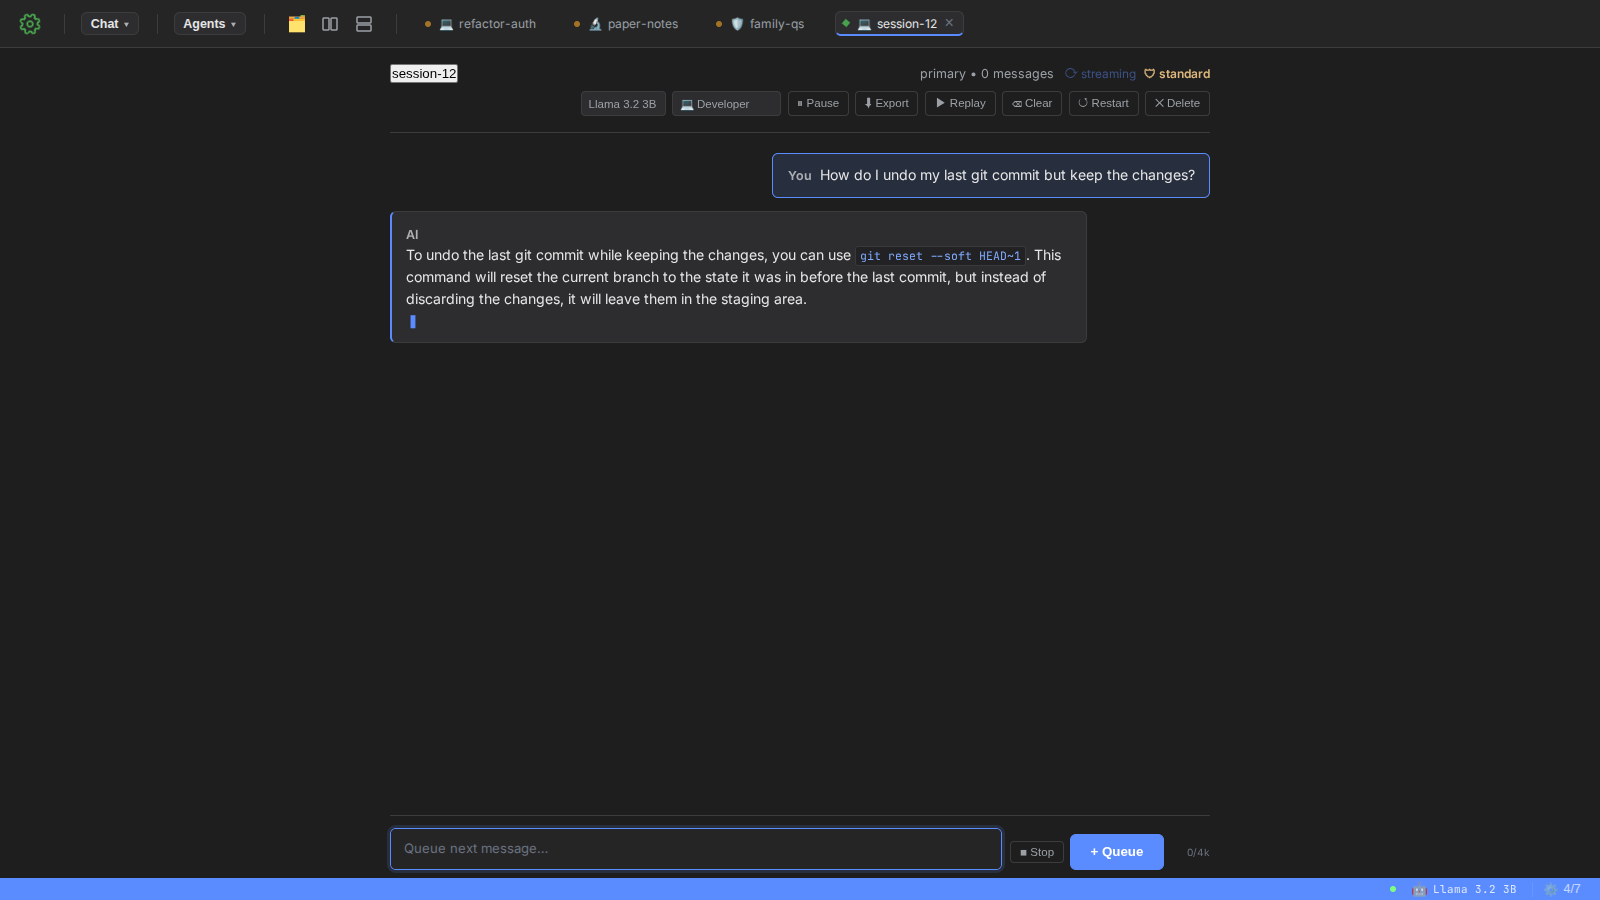
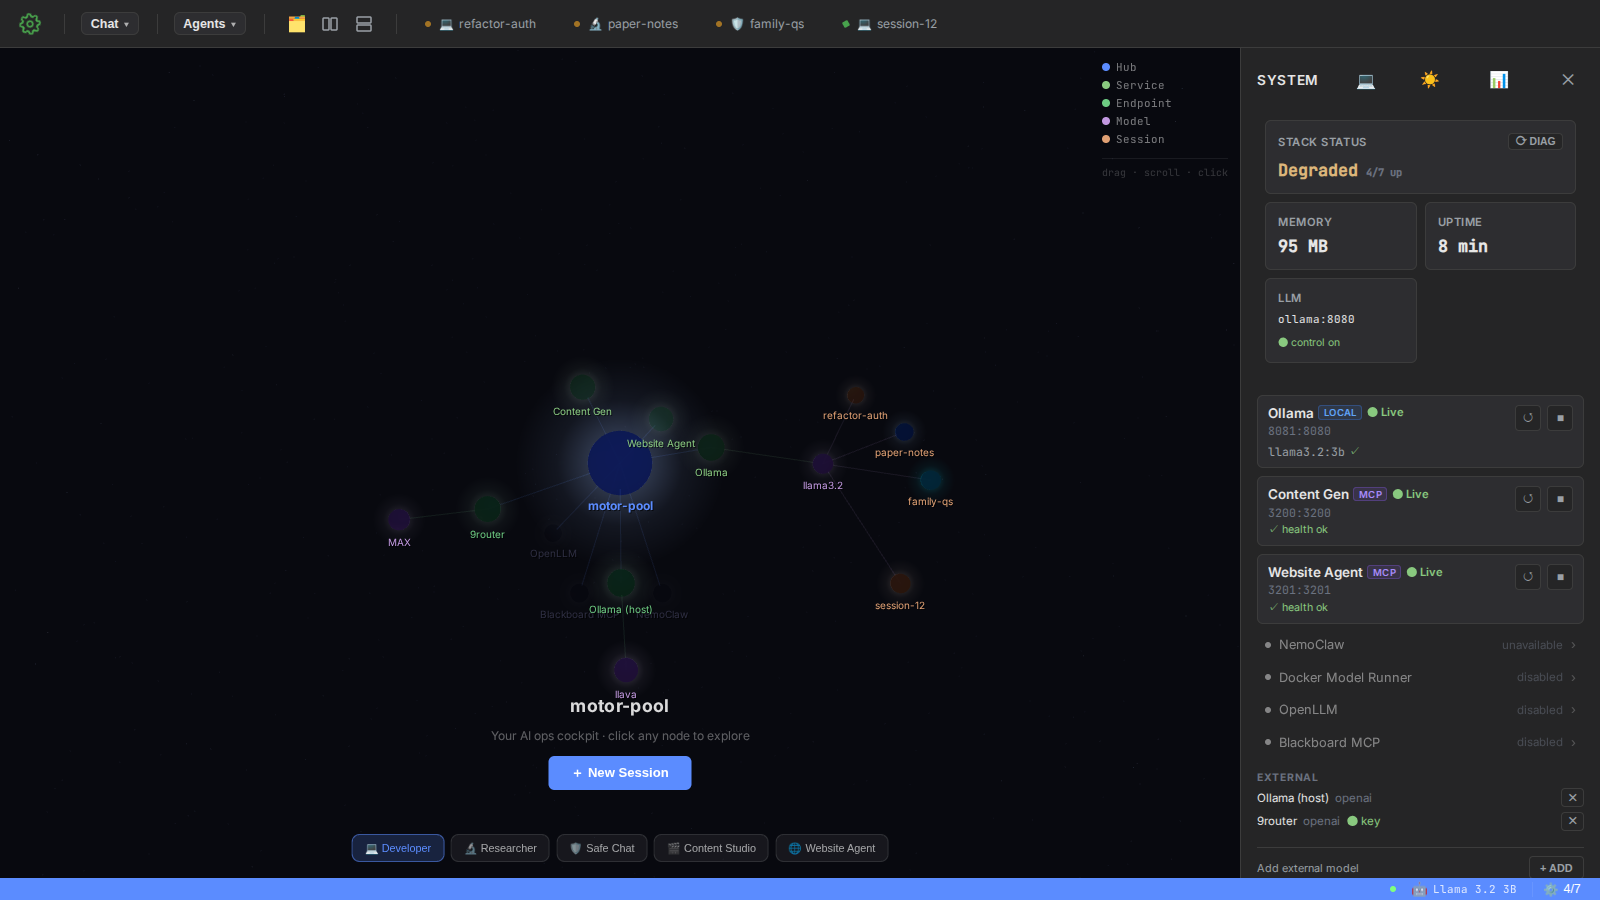
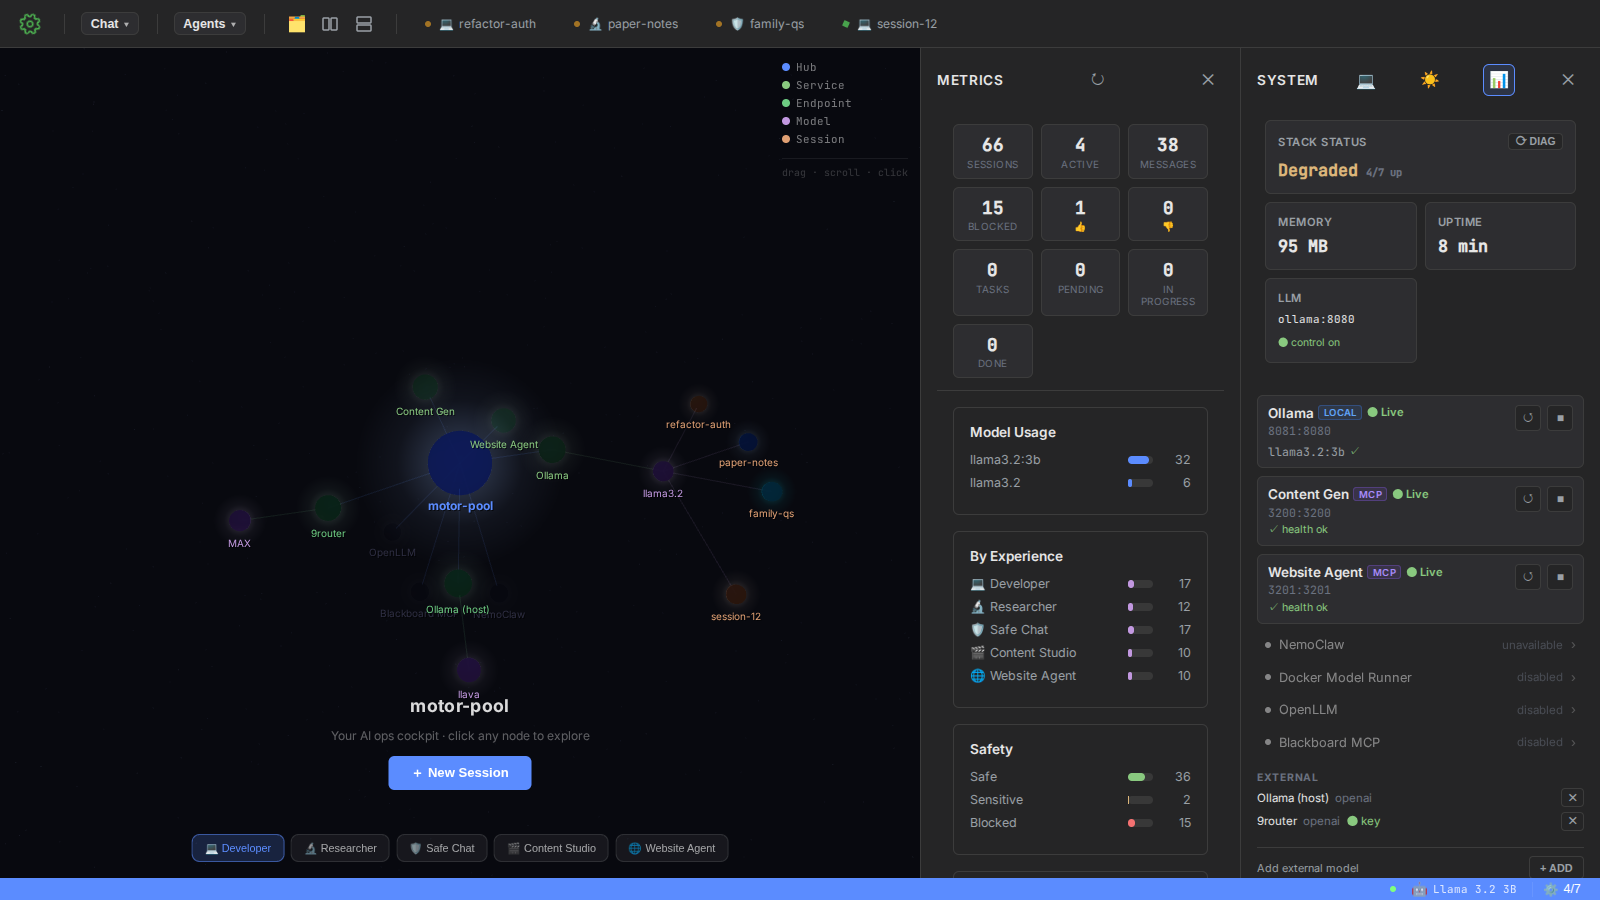
Captured from localhost:3000 with Ollama serving llama3.2:3b on a laptop RTX 3070.
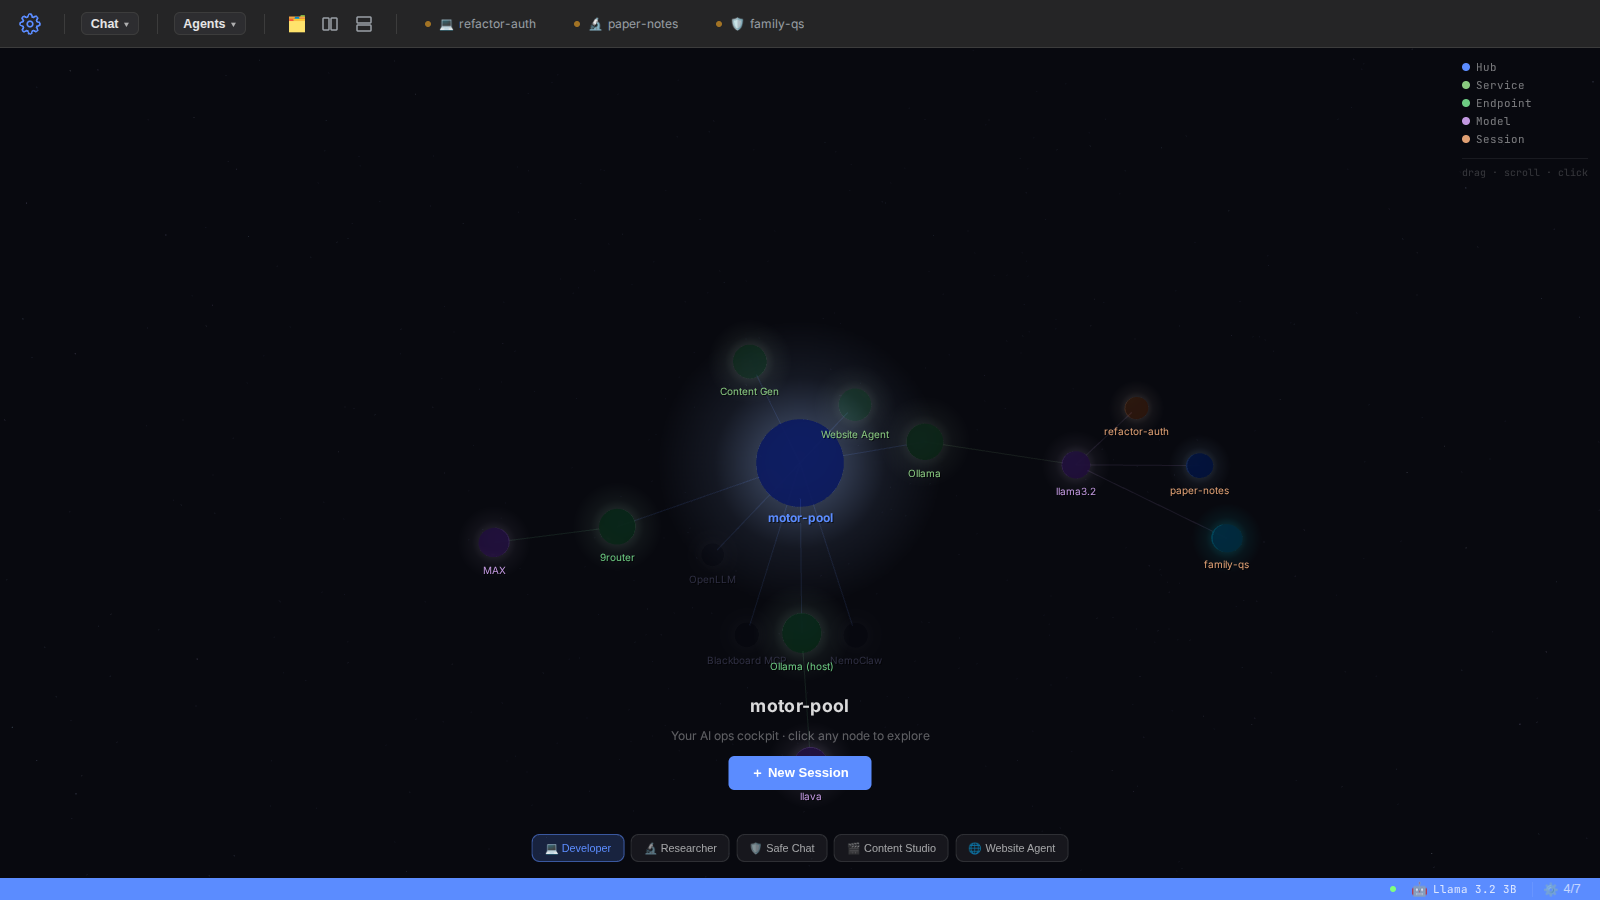
A local-first control room for multi-model AI. Chat with local models, run MCP tool containers, launch parallel agents and watch the whole stack live, all from one Docker stack on your own machine.
Running local LLMs usually means juggling Ollama, a chat UI, container logs and a pile of scripts. motor-pool puts them in one place.
Runs on your machine with Docker. Prompts go to your own models unless you add an external endpoint.
Ollama, Docker Model Runner, OpenLLM and any OpenAI-compatible endpoint, side by side.
Live service state, metrics, a WebSocket event stream and OpenTelemetry traces to Jaeger.
Drop-in plugins, a declarative MCP registry and tool containers you start on demand.
A Three.js map of your hub, services, models and sessions. Click any node to inspect it or start, stop, restart and pull models.
Persistent sessions with streaming replies, message history, replay mode and export, under a per-experience safety policy.
Hardware detection picks a minimal, laptop or desktop profile, and an opt-in NVIDIA overlay runs Ollama on CUDA.
Add OpenRouter, vLLM, LM Studio or any OpenAI-compatible API with CUSTOM_LLM_ENDPOINTS. Keys stay server-side.
Start, stop and restart containers from the System panel through docker compose, with live health and port info per service.
Declare tools once in mcp-registry.json. motor-pool lists them with live health and starts them just in time.
Drop a manifest into config/plugins/ and its tools join the model's tool list as plugin__tool calls.
Launch agents into their own tmux window and git worktree so several can work on one repo without colliding. Opt-in, with an allowlist.
Mount a project folder, then browse, edit and commit from a split-pane editor with a terminal, git log and artifacts tab.
Session, safety, feedback and error telemetry, a live event stream, and OTLP traces to Jaeger.
Strict, standard and research policies per experience, with prompt-injection patterns, PII redaction and output sanitization.
An opt-in warmup service pre-loads your primary model during docker compose up, so your first message doesn't wait on a cold load.
Captured from localhost:3000 with Ollama serving llama3.2:3b on a laptop RTX 3070.
The Express + React dashboard routes each session to an endpoint, applies the experience's policy, and streams events to the UI. Everything else is a container you control.
Hub, chat, System and Metrics panels, workspace IDE
Sessions · experience routing · safety policies · event bus · plugins · OpenTelemetry
Ollama (CPU/CUDA) · Docker Model Runner · OpenLLM · your endpoints
content-gen · website · bb-mcp · plugins
Postgres · encrypted endpoint store · Jaeger
You need Docker Desktop (or Docker Engine with Compose). The minimal stack is the dashboard, Ollama and Postgres, and fits on a 16 GB machine.
$ git clone https://github.com/nitsuah/motor-pool.git
$ cd motor-pool
$ cp .env.example .env && cp .env config/.env
$ docker compose -f config/docker-compose.yml up -d
# NVIDIA GPU? add the overlay:
$ docker compose -f config/docker-compose.yml \
    -f config/docker-compose.gpu.yml up -d
ollama-init pulls automatically.tools, observability or sandbox profiles.The full plan is in ROADMAP.md.